Neurocle Neuro-R Runtime Library
Highlights
Neurocle Neuro-R is a runtime library for deploying trained deep learning vision models into production inspection systems.
Models developed with Neuro-T or Neuro-T Engine can be integrated into machine vision applications for real-time inference across CPU, GPU, NPU, and embedded processing platforms.
From Trained Model to Production Inspection
STEP 1
Train
Develop and validate the inspection model in Neuro-T or Neuro-T Engine.
→
STEP 2
Integrate
Use Neuro-R APIs to connect the trained model with the machine vision application.
→
STEP 3
Inspect
Run the trained model against live production images or video streams in real time.
Flexible Model Deployment
Production inspection systems have different requirements for speed, processing power, enclosure space, and power consumption. Neuro-R allows the runtime hardware to be selected around the application instead of forcing every inspection system onto the same computing platform.
This gives machine builders and system integrators flexibility to deploy Neurocle models on conventional industrial PCs, GPU workstations, AI accelerators, or compact embedded platforms.
Supported Processing Platforms
GPU
CPU
NPU
Embedded Board
Select the processing architecture based on the application’s throughput, cost, power, and mechanical requirements.
Programming Languages

C++
Neuro-R API integration

C#
Neuro-R API integration

Python
Neuro-R API integration
Features
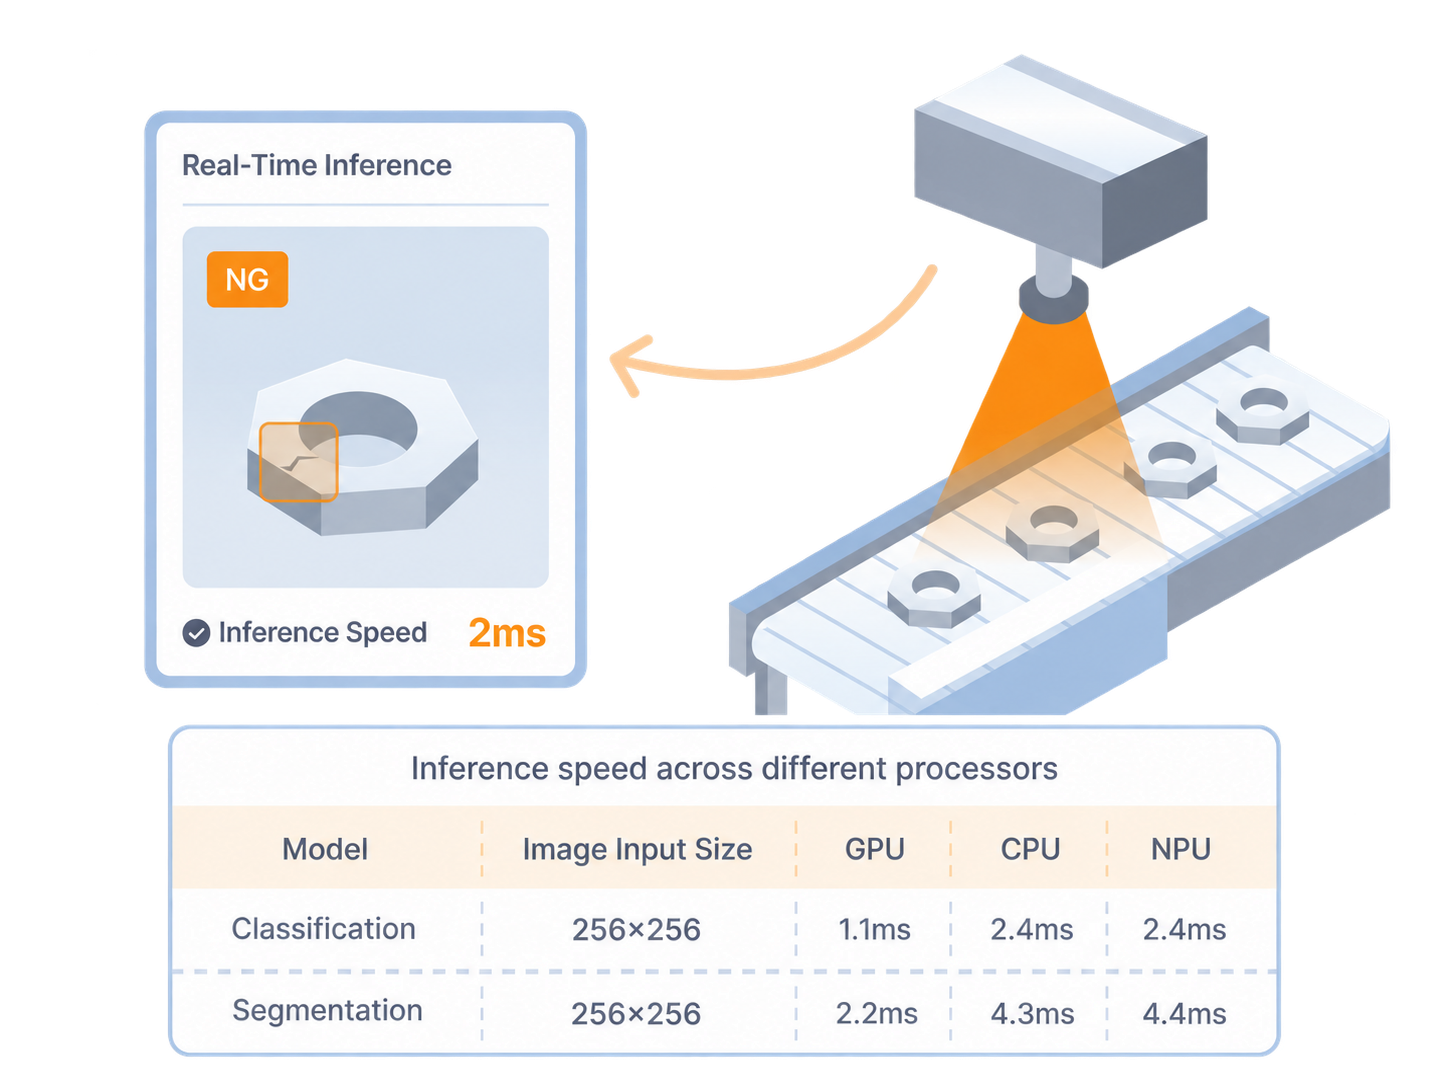
Model Optimization for High-Speed Inspection
Optimize trained models and processor performance around the inference speed required by high-throughput production inspection systems.
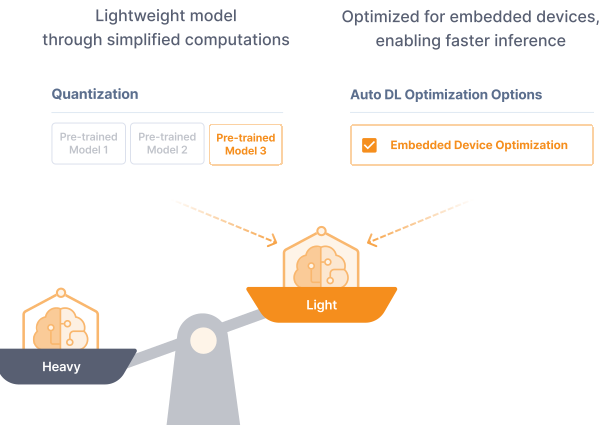
Model Optimization for Edge Devices
Use quantization and embedded-device optimization to create lightweight deployment models for systems with limited processing power, space, or power availability.
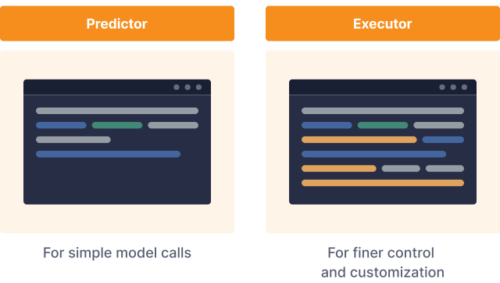
Flexible Implementation Methods
Use Predictor or Executor implementation structures depending on the level of runtime integration and application control required.
Predictor
Designed for straightforward model execution where the application loads the model, supplies image data, and receives inference results.
Executor
Provides greater control for applications requiring customized inference workflows and integration behavior.
Applications
Defect Inspection
Classification
Object Detection
Segmentation
Semiconductor
Battery
Automotive
Pharmaceutical